%20%20--%3E%0A%3Csvg%20width%3D%22913%22%20height%3D%22292%22%20version%3D%221.1%22%20id%3D%22Layer_1%22%20xmlns%3D%22http%3A%2F%2Fwww.w3.org%2F2000%2Fsvg%22%20xmlns%3Axlink%3D%22http%3A%2F%2Fwww.w3.org%2F1999%2Fxlink%22%20x%3D%220px%22%20y%3D%220px%22%0A%09%20viewBox%3D%2293.51%20166.38%20456.61%20146.15%22%20%20xml%3Aspace%3D%22preserve%22%3E%0A%3Cg%3E%0A%09%3Cpath%20stroke%3D%22%2317191C%22%20fill%3D%22%2317191C%22%20stroke-linecap%3D%22round%22%20stroke-linejoin%3D%22round%22%20stroke-miterlimit%3D%2210%22%20d%3D%22M538.569%2C174.679%0A%09%09c-1.453%2C0.551-2.921%2C1.302-4.098%2C2.3c-4.06%2C3.444-8.158%2C6.87-11.95%2C10.598c-18.233%2C17.929-34.971%2C37.204-51.035%2C57.079%0A%09%09c-0.909%2C1.125-1.924%2C2.245-3.102%2C3.06c-7.23%2C4.999-15.157%2C8.547-23.608%2C10.901c-1.781%2C0.496-3.687%2C0.754-5.534%2C0.748%0A%09%09c-2.912-0.008-4.191-1.702-3.506-4.507c0.341-1.398%2C0.93-2.778%2C1.641-4.033c1.151-2.033%2C2.556-3.923%2C3.731-5.944%0A%09%09c0.537-0.923%2C1.887-1.996%2C0.692-3.017c-0.45-0.384-2.016%2C0.244-2.899%2C0.727c-1.47%2C0.804-2.801%2C1.864-4.253%2C2.859%0A%09%09c-2.031-2.727-4.723-2.911-7.593-1.972c-1.823%2C0.597-3.645%2C1.301-5.323%2C2.221c-3.789%2C2.078-7.429%2C4.429-11.238%2C6.467%0A%09%09c-4.86%2C2.6-9.911%2C4.754-15.492%2C5.291c-2.817%2C0.271-3.375-0.38-2.78-3.172c0.644-3.026%2C1.416-6.035%2C1.871-9.09%0A%09%09c0.381-2.561-0.895-3.716-3.407-3.103c-2.136%2C0.521-4.359%2C1.139-6.22%2C2.253c-6.066%2C3.631-11.983%2C7.512-17.962%2C11.289%0A%09%09c-0.481%2C0.304-1%2C0.547-1.501%2C0.818c-0.088-0.682%2C0.013-1.078%2C0.243-1.374c4.748-6.111%2C9.635-12.098%2C15.671-17.024%0A%09%09c0.544-0.444%2C1.187-0.798%2C1.631-1.323c0.279-0.33%2C0.273-0.901%2C0.396-1.364c-0.519-0.016-1.053-0.111-1.553-0.02%0A%09%09c-0.309%2C0.056-0.591%2C0.367-0.845%2C0.607c-2.768%2C2.606-5.531%2C5.218-8.288%2C7.835c-1.142%2C1.084-2.114%2C2.442-3.43%2C3.229%0A%09%09c-4.109%2C2.458-8.212%2C5.006-12.575%2C6.936c-3.588%2C1.587-7.495%2C2.569-11.351%2C3.395c-3.136%2C0.672-3.755-0.251-3.044-3.467%0A%09%09c0.605-2.737%2C1.254-5.465%2C1.817-8.211c0.579-2.822-0.764-4.208-3.614-3.533c-1.971%2C0.467-4.027%2C1.024-5.739%2C2.052%0A%09%09c-6.061%2C3.639-11.989%2C7.501-17.973%2C11.268c-0.574%2C0.361-1.192%2C0.654-1.79%2C0.978c-0.071-0.699%2C0.046-1.092%2C0.283-1.392%0A%09%09c5.078-6.444%2C10.212-12.834%2C16.774-17.897c0.482-0.372%2C0.611-1.203%2C0.904-1.82c-0.666%2C0.108-1.548-0.02-1.964%2C0.361%0A%09%09c-3.317%2C3.043-6.533%2C6.195-9.807%2C9.286c-1.185%2C1.118-2.338%2C2.316-3.684%2C3.21c-7.828%2C5.202-16.464%2C8.594-25.548%2C10.785%0A%09%09c-2.547%2C0.614-5.327%2C0.614-7.962%2C0.405c-2.538-0.201-3.629-2.047-2.709-4.402c0.728-1.864%2C1.968-3.541%2C3.101-5.22%0A%09%09c0.206-0.306%2C1.024-0.381%2C1.506-0.288c3.123%2C0.604%2C6.049%2C0.397%2C8.647-1.69c1.306-1.049%2C2.131-2.336%2C1.432-3.957%0A%09%09c-0.699-1.62-2.242-1.642-3.775-1.401c-2.846%2C0.448-4.874%2C2.344-7.174%2C3.845c-8.31%2C5.42-17.164%2C9.783-26.663%2C12.709%0A%09%09c-2.204%2C0.679-4.582%2C0.993-6.893%2C1.075c-2.423%2C0.086-3.431-1.241-3.162-3.567c0.079-0.687%2C0.302-1.366%2C0.527-2.025%0A%09%09c0.809-2.375%2C1.795-4.701%2C2.438-7.12c0.797-2.996-0.853-4.569-3.739-3.492c-2.054%2C0.766-4.177%2C1.745-5.819%2C3.153%0A%09%09c-7.018%2C6.014-13.868%2C12.224-20.782%2C18.36c-0.52%2C0.461-1.058%2C0.903-1.588%2C1.354c-0.114-0.103-0.229-0.205-0.343-0.307%0A%09%09c0.336-0.647%2C0.598-1.347%2C1.019-1.934c3.817-5.328%2C7.653-10.642%2C11.515-15.938c0.366-0.502%2C0.908-0.91%2C1.438-1.255%0A%09%09c18.004-11.719%2C34.253-25.54%2C49.035-41.092c6.577-6.92%2C12.982-14.013%2C18.027-22.183c1.037-1.679%2C2.026-3.468%2C2.567-5.341%0A%09%09c0.302-1.047-0.026-2.623-0.68-3.511c-0.827-1.123-2.332-0.852-3.543-0.192c-1.076%2C0.586-2.193%2C1.153-3.133%2C1.923%0A%09%09c-2.851%2C2.337-5.742%2C4.643-8.408%2C7.182c-17.503%2C16.672-33.501%2C34.738-48.767%2C53.442c-4.973%2C6.092-10.053%2C11.842-17.166%2C15.455%0A%09%09c-3.382%2C1.718-6.706%2C3.563-10.156%2C5.13c-1.392%2C0.633-3.04%2C0.792-4.594%2C0.956c-1.449%2C0.152-2.371-0.521-2.183-2.172%0A%09%09c0.119-1.044%2C0.246-2.088%2C0.323-3.135c0.331-4.51-0.973-5.513-5.114-3.526c-3.628%2C1.74-7.065%2C3.877-10.599%2C5.816%0A%09%09c-0.542%2C0.297-1.152%2C0.471-1.73%2C0.703c0.056-0.925%2C0.336-1.49%2C0.668-2.024c1.604-2.585%2C3.283-5.126%2C4.812-7.755%0A%09%09c0.906-1.558%2C1.698-3.207%2C2.33-4.894c0.674-1.797-0.236-3.288-2.139-3.31c-1.521-0.018-3.248%2C0.161-4.534%2C0.879%0A%09%09c-2.95%2C1.648-5.803%2C3.526-8.486%2C5.585c-5.387%2C4.134-10.627%2C8.459-15.949%2C12.679c-0.599%2C0.475-1.331%2C0.782-2.001%2C1.167%0A%09%09c-0.115-0.16-0.229-0.319-0.344-0.479c0.336-0.592%2C0.593-1.25%2C1.02-1.766c3.538-4.278%2C7.105-8.531%2C10.671-12.785%0A%09%09c0.299-0.357%2C0.745-0.614%2C0.97-1.005c0.174-0.301%2C0.279-0.922%2C0.113-1.076c-0.284-0.264-0.827-0.412-1.218-0.348%0A%09%09c-0.348%2C0.057-0.666%2C0.44-0.949%2C0.727c-4.703%2C4.764-9.006%2C9.851-12.485%2C15.594c-0.362%2C0.597-0.798%2C1.219-0.907%2C1.877%0A%09%09c-0.103%2C0.618-0.035%2C1.578%2C0.354%2C1.884c0.46%2C0.362%2C1.46%2C0.44%2C2.021%2C0.187c1.156-0.522%2C2.239-1.266%2C3.242-2.059%0A%09%09c5.33-4.209%2C10.548-8.565%2C15.965-12.657c3.065-2.315%2C6.396-4.292%2C9.704-6.257c0.737-0.438%2C1.883-0.187%2C2.84-0.253%0A%09%09c-0.131%2C0.923-0.063%2C1.938-0.435%2C2.75c-0.776%2C1.695-1.734%2C3.315-2.709%2C4.91c-1.464%2C2.395-3.037%2C4.724-4.496%2C7.122%0A%09%09c-0.447%2C0.735-0.806%2C1.579-0.972%2C2.419c-0.292%2C1.482%2C0.464%2C2.193%2C1.88%2C1.668c1.462-0.543%2C2.844-1.333%2C4.207-2.109%0A%09%09c3.2-1.821%2C6.34-3.748%2C9.566-5.521c0.838-0.461%2C1.9-0.513%2C2.99-0.786c-0.175%2C2.374-0.435%2C4.348-0.436%2C6.322%0A%09%09c-0.001%2C2.282%2C1.081%2C3.517%2C3.342%2C3.343c2.464-0.189%2C5.086-0.498%2C7.286-1.516c4.652-2.153%2C9.075-4.801%2C13.704-7.307%0A%09%09c-0.308%2C0.439-0.612%2C0.852-0.894%2C1.279c-2.865%2C4.342-5.755%2C8.668-8.564%2C13.046c-0.589%2C0.918-1.002%2C2-1.254%2C3.064%0A%09%09c-0.137%2C0.579%2C0.037%2C1.571%2C0.434%2C1.84c0.385%2C0.261%2C1.323-0.014%2C1.859-0.326c0.691-0.402%2C1.231-1.068%2C1.822-1.634%0A%09%09c5.245-5.021%2C10.361-10.185%2C15.776-15.015c3.257-2.905%2C6.928-5.361%2C10.526-7.857c0.843-0.585%2C2.14-0.517%2C3.228-0.75%0A%09%09c-0.154%2C1.061-0.184%2C2.159-0.486%2C3.176c-0.764%2C2.568-1.884%2C5.051-2.428%2C7.658c-0.659%2C3.164%2C1.057%2C5.349%2C4.276%2C5.502%0A%09%09c2.186%2C0.104%2C4.463-0.104%2C6.588-0.624c7.614-1.864%2C14.511-5.491%2C21.409-9.084c0.53-0.276%2C1.074-0.524%2C1.841-0.897%0A%09%09c-0.421%2C0.94-0.733%2C1.565-0.985%2C2.212c-1.629%2C4.197%2C0.212%2C7.45%2C4.698%2C7.952c2.007%2C0.225%2C4.119%2C0.21%2C6.099-0.156%0A%09%09c8.113-1.497%2C15.707-4.489%2C22.95-8.406c0.467-0.253%2C0.949-0.48%2C1.73-0.874c-1.614%2C2.355-3.084%2C4.331-4.339%2C6.435%0A%09%09c-0.363%2C0.609-0.107%2C1.586-0.135%2C2.394c0.801-0.096%2C1.748%2C0.049%2C2.374-0.333c1.793-1.096%2C3.413-2.471%2C5.177-3.619%0A%09%09c5.831-3.793%2C11.647-7.614%2C17.58-11.242c1.543-0.943%2C3.47-1.299%2C5.26-1.782c1.016-0.274%2C1.576%2C0.248%2C1.331%2C1.375%0A%09%09c-0.099%2C0.457-0.191%2C0.915-0.297%2C1.37c-0.618%2C2.675-1.279%2C5.341-1.85%2C8.026c-0.665%2C3.13%2C0.652%2C4.737%2C3.867%2C4.676%0A%09%09c1.278-0.024%2C2.571-0.204%2C3.822-0.477c5.826-1.272%2C11.139-3.84%2C16.375-6.589c0.426-0.224%2C0.874-0.408%2C1.691-0.786%0A%09%09c-1.58%2C2.247-2.922%2C4.091-4.19%2C5.984c-0.695%2C1.037-1.855%2C2.301-0.591%2C3.404c1.182%2C1.031%2C2.213-0.347%2C3.196-0.998%0A%09%09c6.874-4.554%2C13.698-9.185%2C20.648-13.618c1.731-1.104%2C3.819-1.755%2C5.829-2.283c1.842-0.483%2C2.227%2C0.076%2C1.807%2C1.916%0A%09%09c-0.688%2C3.019-1.412%2C6.03-2.049%2C9.06c-0.585%2C2.783%2C0.608%2C4.279%2C3.442%2C4.395c0.697%2C0.029%2C1.441%2C0.059%2C2.093-0.141%0A%09%09c4.173-1.279%2C8.328-2.619%2C12.485-3.95c0.551-0.176%2C1.082-0.414%2C1.898-0.729c-0.403%2C0.736-0.647%2C1.133-0.844%2C1.551%0A%09%09c-0.621%2C1.315-1.206%2C2.914-0.026%2C3.912c0.861%2C0.729%2C2.519%2C1.06%2C3.649%2C0.805c1.954-0.441%2C3.935-1.224%2C5.622-2.305%0A%09%09c5.614-3.595%2C11.102-7.386%2C16.638-11.103c0.92-0.618%2C1.839-1.237%2C2.758-1.856c-0.788%2C1.986-1.969%2C3.628-2.665%2C5.455%0A%09%09c-0.712%2C1.869-1.187%2C3.902-1.331%2C5.894c-0.157%2C2.185%2C1.313%2C3.811%2C3.455%2C4.218c1.19%2C0.226%2C2.454%2C0.309%2C3.657%2C0.186%0A%09%09c5.068-0.521%2C9.73-2.451%2C14.331-4.466c3.507-1.536%2C6.898-3.334%2C10.614-5.149c-0.422%2C0.635-0.691%2C1.044-0.966%2C1.45%0A%09%09c-2.591%2C3.826-5.249%2C7.61-7.741%2C11.5c-0.934%2C1.458-1.572%2C3.131-2.151%2C4.775c-0.181%2C0.512%2C0.097%2C1.438%2C0.501%2C1.815%0A%09%09c0.263%2C0.245%2C1.208-0.024%2C1.71-0.307c0.647-0.365%2C1.182-0.949%2C1.721-1.483c1.956-1.936%2C3.805-3.99%2C5.854-5.819%0A%09%09c5.893-5.258%2C11.816-10.485%2C17.842-15.588c1.345-1.139%2C3.12-1.818%2C4.775-2.525c1.104-0.472%2C1.76%2C0.084%2C1.374%2C1.309%0A%09%09c-0.525%2C1.669-1.269%2C3.273-1.732%2C4.957c-0.551%2C2.005-1.184%2C4.054-1.268%2C6.104c-0.097%2C2.368%2C1.38%2C3.81%2C3.778%2C4.016%0A%09%09c1.73%2C0.149%2C3.555%2C0.204%2C5.229-0.176c10.868-2.464%2C20.485-7.78%2C29.928-13.445c0.375-0.225%2C0.471-0.915%2C0.698-1.388%0A%09%09c-0.572-0.065-1.154-0.224-1.712-0.163c-0.368%2C0.04-0.7%2C0.398-1.049%2C0.614c-7.434%2C4.6-15.223%2C8.484-23.555%2C11.154%0A%09%09c-2.641%2C0.846-5.451%2C1.368-8.217%2C1.563c-2.748%2C0.194-3.899-1.561-3.252-4.255c0.122-0.508%2C0.346-0.992%2C0.52-1.488%0A%09%09c0.794-2.258%2C1.755-4.476%2C2.305-6.792c0.25-1.049%2C0.051-2.653-0.622-3.337c-0.584-0.593-2.268-0.608-3.214-0.236%0A%09%09c-1.991%2C0.782-4.068%2C1.692-5.666%2C3.065c-7.01%2C6.024-13.861%2C12.233-20.772%2C18.371c-0.524%2C0.465-1.067%2C0.909-1.601%2C1.363%0A%09%09c-0.116-0.1-0.233-0.199-0.349-0.299c0.335-0.645%2C0.598-1.341%2C1.016-1.927c3.706-5.192%2C7.426-10.373%2C11.181-15.53%0A%09%09c0.471-0.647%2C1.1-1.235%2C1.771-1.674c20.852-13.66%2C39.424-29.938%2C55.89-48.634c4.727-5.366%2C9.27-10.882%2C12.66-17.223%0A%09%09c0.669-1.252%2C1.139-2.717%2C1.271-4.125C542.312%2C175.139%2C540.628%2C173.898%2C538.569%2C174.679z%20M293.981%2C244.92%0A%09%09c-1.55%2C2.561-4.34%2C3.534-7.498%2C2.705C288.263%2C245.188%2C292.097%2C243.758%2C293.981%2C244.92z%20M248.437%2C227.56%0A%09%09c12.131-14.045%2C24.535-27.843%2C37.875-40.761c3.271-3.167%2C6.804-6.078%2C10.36-8.927c0.926-0.742%2C2.391-0.812%2C3.608-1.19%0A%09%09c-0.186%2C1.255-0.092%2C2.641-0.604%2C3.744c-2.639%2C5.683-6.643%2C10.459-10.689%2C15.148c-15.378%2C17.818-33%2C33.148-52.203%2C46.7%0A%09%09c-0.138%2C0.097-0.289%2C0.177-0.434%2C0.264c-0.093-0.069-0.186-0.138-0.279-0.207C240.188%2C237.404%2C244.24%2C232.419%2C248.437%2C227.56z%0A%09%09%20M415.185%2C258.07c-0.957%2C0.581-2.187%2C0.79-3.322%2C0.978c-1.224%2C0.203-1.609-0.534-1.193-1.606c0.248-0.64%2C0.62-1.272%2C1.075-1.784%0A%09%09c4.271-4.81%2C9.483-8.261%2C15.534-10.39c2.689-0.946%2C4.195-0.509%2C5.849%2C1.659C427.067%2C250.708%2C421.158%2C254.443%2C415.185%2C258.07z%0A%09%09%20M539.525%2C180.311c-2.66%2C5.675-6.643%2C10.468-10.688%2C15.17c-15.286%2C17.771-32.86%2C33.008-51.928%2C46.571%0A%09%09c-0.265%2C0.189-0.553%2C0.345-0.831%2C0.517c-0.068-0.073-0.137-0.147-0.205-0.22c2.179-2.638%2C4.341-5.289%2C6.538-7.91%0A%09%09c13.891-16.575%2C28.319-32.662%2C43.806-47.769c3.261-3.181%2C6.826-6.063%2C10.389-8.91c0.876-0.7%2C2.294-0.724%2C3.462-1.059%0A%09%09C539.903%2C177.912%2C540.02%2C179.255%2C539.525%2C180.311z%22%2F%3E%0A%09%3Cpath%20stroke%3D%22%2317191C%22%20fill%3D%22%2317191C%22%20stroke-linecap%3D%22round%22%20stroke-linejoin%3D%22round%22%20stroke-miterlimit%3D%2210%22%20d%3D%22M164.891%2C223.747%0A%09%09c4.502-0.235%2C9.013-0.436%2C13.52-0.429c9.663%2C0.016%2C19.326%2C0.179%2C28.989%2C0.23c0.494%2C0.003%2C0.991-0.475%2C1.486-0.73%0A%09%09c-0.488-0.336-0.974-0.96-1.466-0.965c-12.297-0.126-24.594-0.196-36.892-0.247c-1.619-0.007-3.239%2C0.142-5.293%2C0.24%0A%09%09c0.609-0.742%2C0.891-1.11%2C1.198-1.455c8.602-9.669%2C17.216-19.327%2C25.777-29.032c0.422-0.478%2C0.371-1.373%2C0.541-2.074%0A%09%09c-0.635%2C0.225-1.481%2C0.263-1.875%2C0.704c-9.162%2C10.267-18.263%2C20.59-27.43%2C30.854c-0.545%2C0.61-1.526%2C1.095-2.34%2C1.154%0A%09%09c-3.736%2C0.273-7.496%2C0.242-11.227%2C0.56c-10.083%2C0.859-20.158%2C1.823-30.228%2C2.823c-0.523%2C0.052-0.975%2C0.827-1.459%2C1.266%0A%09%09c0.571%2C0.226%2C1.164%2C0.688%2C1.71%2C0.638c2.385-0.22%2C4.749-0.667%2C7.134-0.89c7.515-0.703%2C15.032-1.383%2C22.555-1.988%0A%09%09c3.584-0.288%2C7.184-0.387%2C11.162-0.592c-0.505%2C0.655-0.732%2C0.969-0.978%2C1.266c-3.84%2C4.65-7.731%2C9.259-11.516%2C13.953%0A%09%09c-16.026%2C19.874-31.573%2C40.104-45.334%2C61.644c-0.502%2C0.786-0.996%2C1.594-1.353%2C2.45c-0.14%2C0.335-0.034%2C1%2C0.216%2C1.208%0A%09%09c0.273%2C0.227%2C0.91%2C0.25%2C1.264%2C0.089c0.448-0.204%2C0.891-0.618%2C1.126-1.055c0.718-1.335%2C1.204-2.808%2C2.011-4.081%0A%09%09c16.722-26.362%2C36.167-50.669%2C56.323-74.433C163.034%2C224.24%2C164.07%2C223.79%2C164.891%2C223.747z%22%2F%3E%0A%3C%2Fg%3E%0A%3C%2Fsvg%3E)
%20%20--%3E%0A%3Csvg%20width%3D%22913%22%20height%3D%22292%22%20version%3D%221.1%22%20id%3D%22Layer_1%22%20xmlns%3D%22http%3A%2F%2Fwww.w3.org%2F2000%2Fsvg%22%20xmlns%3Axlink%3D%22http%3A%2F%2Fwww.w3.org%2F1999%2Fxlink%22%20x%3D%220px%22%20y%3D%220px%22%0A%09%20viewBox%3D%2293.51%20166.38%20456.61%20146.15%22%20%20xml%3Aspace%3D%22preserve%22%3E%0A%3Cg%3E%0A%09%3Cpath%20stroke%3D%22%23F7F4EE%22%20fill%3D%22%23F7F4EE%22%20stroke-linecap%3D%22round%22%20stroke-linejoin%3D%22round%22%20stroke-miterlimit%3D%2210%22%20d%3D%22M538.569%2C174.679%0A%09%09c-1.453%2C0.551-2.921%2C1.302-4.098%2C2.3c-4.06%2C3.444-8.158%2C6.87-11.95%2C10.598c-18.233%2C17.929-34.971%2C37.204-51.035%2C57.079%0A%09%09c-0.909%2C1.125-1.924%2C2.245-3.102%2C3.06c-7.23%2C4.999-15.157%2C8.547-23.608%2C10.901c-1.781%2C0.496-3.687%2C0.754-5.534%2C0.748%0A%09%09c-2.912-0.008-4.191-1.702-3.506-4.507c0.341-1.398%2C0.93-2.778%2C1.641-4.033c1.151-2.033%2C2.556-3.923%2C3.731-5.944%0A%09%09c0.537-0.923%2C1.887-1.996%2C0.692-3.017c-0.45-0.384-2.016%2C0.244-2.899%2C0.727c-1.47%2C0.804-2.801%2C1.864-4.253%2C2.859%0A%09%09c-2.031-2.727-4.723-2.911-7.593-1.972c-1.823%2C0.597-3.645%2C1.301-5.323%2C2.221c-3.789%2C2.078-7.429%2C4.429-11.238%2C6.467%0A%09%09c-4.86%2C2.6-9.911%2C4.754-15.492%2C5.291c-2.817%2C0.271-3.375-0.38-2.78-3.172c0.644-3.026%2C1.416-6.035%2C1.871-9.09%0A%09%09c0.381-2.561-0.895-3.716-3.407-3.103c-2.136%2C0.521-4.359%2C1.139-6.22%2C2.253c-6.066%2C3.631-11.983%2C7.512-17.962%2C11.289%0A%09%09c-0.481%2C0.304-1%2C0.547-1.501%2C0.818c-0.088-0.682%2C0.013-1.078%2C0.243-1.374c4.748-6.111%2C9.635-12.098%2C15.671-17.024%0A%09%09c0.544-0.444%2C1.187-0.798%2C1.631-1.323c0.279-0.33%2C0.273-0.901%2C0.396-1.364c-0.519-0.016-1.053-0.111-1.553-0.02%0A%09%09c-0.309%2C0.056-0.591%2C0.367-0.845%2C0.607c-2.768%2C2.606-5.531%2C5.218-8.288%2C7.835c-1.142%2C1.084-2.114%2C2.442-3.43%2C3.229%0A%09%09c-4.109%2C2.458-8.212%2C5.006-12.575%2C6.936c-3.588%2C1.587-7.495%2C2.569-11.351%2C3.395c-3.136%2C0.672-3.755-0.251-3.044-3.467%0A%09%09c0.605-2.737%2C1.254-5.465%2C1.817-8.211c0.579-2.822-0.764-4.208-3.614-3.533c-1.971%2C0.467-4.027%2C1.024-5.739%2C2.052%0A%09%09c-6.061%2C3.639-11.989%2C7.501-17.973%2C11.268c-0.574%2C0.361-1.192%2C0.654-1.79%2C0.978c-0.071-0.699%2C0.046-1.092%2C0.283-1.392%0A%09%09c5.078-6.444%2C10.212-12.834%2C16.774-17.897c0.482-0.372%2C0.611-1.203%2C0.904-1.82c-0.666%2C0.108-1.548-0.02-1.964%2C0.361%0A%09%09c-3.317%2C3.043-6.533%2C6.195-9.807%2C9.286c-1.185%2C1.118-2.338%2C2.316-3.684%2C3.21c-7.828%2C5.202-16.464%2C8.594-25.548%2C10.785%0A%09%09c-2.547%2C0.614-5.327%2C0.614-7.962%2C0.405c-2.538-0.201-3.629-2.047-2.709-4.402c0.728-1.864%2C1.968-3.541%2C3.101-5.22%0A%09%09c0.206-0.306%2C1.024-0.381%2C1.506-0.288c3.123%2C0.604%2C6.049%2C0.397%2C8.647-1.69c1.306-1.049%2C2.131-2.336%2C1.432-3.957%0A%09%09c-0.699-1.62-2.242-1.642-3.775-1.401c-2.846%2C0.448-4.874%2C2.344-7.174%2C3.845c-8.31%2C5.42-17.164%2C9.783-26.663%2C12.709%0A%09%09c-2.204%2C0.679-4.582%2C0.993-6.893%2C1.075c-2.423%2C0.086-3.431-1.241-3.162-3.567c0.079-0.687%2C0.302-1.366%2C0.527-2.025%0A%09%09c0.809-2.375%2C1.795-4.701%2C2.438-7.12c0.797-2.996-0.853-4.569-3.739-3.492c-2.054%2C0.766-4.177%2C1.745-5.819%2C3.153%0A%09%09c-7.018%2C6.014-13.868%2C12.224-20.782%2C18.36c-0.52%2C0.461-1.058%2C0.903-1.588%2C1.354c-0.114-0.103-0.229-0.205-0.343-0.307%0A%09%09c0.336-0.647%2C0.598-1.347%2C1.019-1.934c3.817-5.328%2C7.653-10.642%2C11.515-15.938c0.366-0.502%2C0.908-0.91%2C1.438-1.255%0A%09%09c18.004-11.719%2C34.253-25.54%2C49.035-41.092c6.577-6.92%2C12.982-14.013%2C18.027-22.183c1.037-1.679%2C2.026-3.468%2C2.567-5.341%0A%09%09c0.302-1.047-0.026-2.623-0.68-3.511c-0.827-1.123-2.332-0.852-3.543-0.192c-1.076%2C0.586-2.193%2C1.153-3.133%2C1.923%0A%09%09c-2.851%2C2.337-5.742%2C4.643-8.408%2C7.182c-17.503%2C16.672-33.501%2C34.738-48.767%2C53.442c-4.973%2C6.092-10.053%2C11.842-17.166%2C15.455%0A%09%09c-3.382%2C1.718-6.706%2C3.563-10.156%2C5.13c-1.392%2C0.633-3.04%2C0.792-4.594%2C0.956c-1.449%2C0.152-2.371-0.521-2.183-2.172%0A%09%09c0.119-1.044%2C0.246-2.088%2C0.323-3.135c0.331-4.51-0.973-5.513-5.114-3.526c-3.628%2C1.74-7.065%2C3.877-10.599%2C5.816%0A%09%09c-0.542%2C0.297-1.152%2C0.471-1.73%2C0.703c0.056-0.925%2C0.336-1.49%2C0.668-2.024c1.604-2.585%2C3.283-5.126%2C4.812-7.755%0A%09%09c0.906-1.558%2C1.698-3.207%2C2.33-4.894c0.674-1.797-0.236-3.288-2.139-3.31c-1.521-0.018-3.248%2C0.161-4.534%2C0.879%0A%09%09c-2.95%2C1.648-5.803%2C3.526-8.486%2C5.585c-5.387%2C4.134-10.627%2C8.459-15.949%2C12.679c-0.599%2C0.475-1.331%2C0.782-2.001%2C1.167%0A%09%09c-0.115-0.16-0.229-0.319-0.344-0.479c0.336-0.592%2C0.593-1.25%2C1.02-1.766c3.538-4.278%2C7.105-8.531%2C10.671-12.785%0A%09%09c0.299-0.357%2C0.745-0.614%2C0.97-1.005c0.174-0.301%2C0.279-0.922%2C0.113-1.076c-0.284-0.264-0.827-0.412-1.218-0.348%0A%09%09c-0.348%2C0.057-0.666%2C0.44-0.949%2C0.727c-4.703%2C4.764-9.006%2C9.851-12.485%2C15.594c-0.362%2C0.597-0.798%2C1.219-0.907%2C1.877%0A%09%09c-0.103%2C0.618-0.035%2C1.578%2C0.354%2C1.884c0.46%2C0.362%2C1.46%2C0.44%2C2.021%2C0.187c1.156-0.522%2C2.239-1.266%2C3.242-2.059%0A%09%09c5.33-4.209%2C10.548-8.565%2C15.965-12.657c3.065-2.315%2C6.396-4.292%2C9.704-6.257c0.737-0.438%2C1.883-0.187%2C2.84-0.253%0A%09%09c-0.131%2C0.923-0.063%2C1.938-0.435%2C2.75c-0.776%2C1.695-1.734%2C3.315-2.709%2C4.91c-1.464%2C2.395-3.037%2C4.724-4.496%2C7.122%0A%09%09c-0.447%2C0.735-0.806%2C1.579-0.972%2C2.419c-0.292%2C1.482%2C0.464%2C2.193%2C1.88%2C1.668c1.462-0.543%2C2.844-1.333%2C4.207-2.109%0A%09%09c3.2-1.821%2C6.34-3.748%2C9.566-5.521c0.838-0.461%2C1.9-0.513%2C2.99-0.786c-0.175%2C2.374-0.435%2C4.348-0.436%2C6.322%0A%09%09c-0.001%2C2.282%2C1.081%2C3.517%2C3.342%2C3.343c2.464-0.189%2C5.086-0.498%2C7.286-1.516c4.652-2.153%2C9.075-4.801%2C13.704-7.307%0A%09%09c-0.308%2C0.439-0.612%2C0.852-0.894%2C1.279c-2.865%2C4.342-5.755%2C8.668-8.564%2C13.046c-0.589%2C0.918-1.002%2C2-1.254%2C3.064%0A%09%09c-0.137%2C0.579%2C0.037%2C1.571%2C0.434%2C1.84c0.385%2C0.261%2C1.323-0.014%2C1.859-0.326c0.691-0.402%2C1.231-1.068%2C1.822-1.634%0A%09%09c5.245-5.021%2C10.361-10.185%2C15.776-15.015c3.257-2.905%2C6.928-5.361%2C10.526-7.857c0.843-0.585%2C2.14-0.517%2C3.228-0.75%0A%09%09c-0.154%2C1.061-0.184%2C2.159-0.486%2C3.176c-0.764%2C2.568-1.884%2C5.051-2.428%2C7.658c-0.659%2C3.164%2C1.057%2C5.349%2C4.276%2C5.502%0A%09%09c2.186%2C0.104%2C4.463-0.104%2C6.588-0.624c7.614-1.864%2C14.511-5.491%2C21.409-9.084c0.53-0.276%2C1.074-0.524%2C1.841-0.897%0A%09%09c-0.421%2C0.94-0.733%2C1.565-0.985%2C2.212c-1.629%2C4.197%2C0.212%2C7.45%2C4.698%2C7.952c2.007%2C0.225%2C4.119%2C0.21%2C6.099-0.156%0A%09%09c8.113-1.497%2C15.707-4.489%2C22.95-8.406c0.467-0.253%2C0.949-0.48%2C1.73-0.874c-1.614%2C2.355-3.084%2C4.331-4.339%2C6.435%0A%09%09c-0.363%2C0.609-0.107%2C1.586-0.135%2C2.394c0.801-0.096%2C1.748%2C0.049%2C2.374-0.333c1.793-1.096%2C3.413-2.471%2C5.177-3.619%0A%09%09c5.831-3.793%2C11.647-7.614%2C17.58-11.242c1.543-0.943%2C3.47-1.299%2C5.26-1.782c1.016-0.274%2C1.576%2C0.248%2C1.331%2C1.375%0A%09%09c-0.099%2C0.457-0.191%2C0.915-0.297%2C1.37c-0.618%2C2.675-1.279%2C5.341-1.85%2C8.026c-0.665%2C3.13%2C0.652%2C4.737%2C3.867%2C4.676%0A%09%09c1.278-0.024%2C2.571-0.204%2C3.822-0.477c5.826-1.272%2C11.139-3.84%2C16.375-6.589c0.426-0.224%2C0.874-0.408%2C1.691-0.786%0A%09%09c-1.58%2C2.247-2.922%2C4.091-4.19%2C5.984c-0.695%2C1.037-1.855%2C2.301-0.591%2C3.404c1.182%2C1.031%2C2.213-0.347%2C3.196-0.998%0A%09%09c6.874-4.554%2C13.698-9.185%2C20.648-13.618c1.731-1.104%2C3.819-1.755%2C5.829-2.283c1.842-0.483%2C2.227%2C0.076%2C1.807%2C1.916%0A%09%09c-0.688%2C3.019-1.412%2C6.03-2.049%2C9.06c-0.585%2C2.783%2C0.608%2C4.279%2C3.442%2C4.395c0.697%2C0.029%2C1.441%2C0.059%2C2.093-0.141%0A%09%09c4.173-1.279%2C8.328-2.619%2C12.485-3.95c0.551-0.176%2C1.082-0.414%2C1.898-0.729c-0.403%2C0.736-0.647%2C1.133-0.844%2C1.551%0A%09%09c-0.621%2C1.315-1.206%2C2.914-0.026%2C3.912c0.861%2C0.729%2C2.519%2C1.06%2C3.649%2C0.805c1.954-0.441%2C3.935-1.224%2C5.622-2.305%0A%09%09c5.614-3.595%2C11.102-7.386%2C16.638-11.103c0.92-0.618%2C1.839-1.237%2C2.758-1.856c-0.788%2C1.986-1.969%2C3.628-2.665%2C5.455%0A%09%09c-0.712%2C1.869-1.187%2C3.902-1.331%2C5.894c-0.157%2C2.185%2C1.313%2C3.811%2C3.455%2C4.218c1.19%2C0.226%2C2.454%2C0.309%2C3.657%2C0.186%0A%09%09c5.068-0.521%2C9.73-2.451%2C14.331-4.466c3.507-1.536%2C6.898-3.334%2C10.614-5.149c-0.422%2C0.635-0.691%2C1.044-0.966%2C1.45%0A%09%09c-2.591%2C3.826-5.249%2C7.61-7.741%2C11.5c-0.934%2C1.458-1.572%2C3.131-2.151%2C4.775c-0.181%2C0.512%2C0.097%2C1.438%2C0.501%2C1.815%0A%09%09c0.263%2C0.245%2C1.208-0.024%2C1.71-0.307c0.647-0.365%2C1.182-0.949%2C1.721-1.483c1.956-1.936%2C3.805-3.99%2C5.854-5.819%0A%09%09c5.893-5.258%2C11.816-10.485%2C17.842-15.588c1.345-1.139%2C3.12-1.818%2C4.775-2.525c1.104-0.472%2C1.76%2C0.084%2C1.374%2C1.309%0A%09%09c-0.525%2C1.669-1.269%2C3.273-1.732%2C4.957c-0.551%2C2.005-1.184%2C4.054-1.268%2C6.104c-0.097%2C2.368%2C1.38%2C3.81%2C3.778%2C4.016%0A%09%09c1.73%2C0.149%2C3.555%2C0.204%2C5.229-0.176c10.868-2.464%2C20.485-7.78%2C29.928-13.445c0.375-0.225%2C0.471-0.915%2C0.698-1.388%0A%09%09c-0.572-0.065-1.154-0.224-1.712-0.163c-0.368%2C0.04-0.7%2C0.398-1.049%2C0.614c-7.434%2C4.6-15.223%2C8.484-23.555%2C11.154%0A%09%09c-2.641%2C0.846-5.451%2C1.368-8.217%2C1.563c-2.748%2C0.194-3.899-1.561-3.252-4.255c0.122-0.508%2C0.346-0.992%2C0.52-1.488%0A%09%09c0.794-2.258%2C1.755-4.476%2C2.305-6.792c0.25-1.049%2C0.051-2.653-0.622-3.337c-0.584-0.593-2.268-0.608-3.214-0.236%0A%09%09c-1.991%2C0.782-4.068%2C1.692-5.666%2C3.065c-7.01%2C6.024-13.861%2C12.233-20.772%2C18.371c-0.524%2C0.465-1.067%2C0.909-1.601%2C1.363%0A%09%09c-0.116-0.1-0.233-0.199-0.349-0.299c0.335-0.645%2C0.598-1.341%2C1.016-1.927c3.706-5.192%2C7.426-10.373%2C11.181-15.53%0A%09%09c0.471-0.647%2C1.1-1.235%2C1.771-1.674c20.852-13.66%2C39.424-29.938%2C55.89-48.634c4.727-5.366%2C9.27-10.882%2C12.66-17.223%0A%09%09c0.669-1.252%2C1.139-2.717%2C1.271-4.125C542.312%2C175.139%2C540.628%2C173.898%2C538.569%2C174.679z%20M293.981%2C244.92%0A%09%09c-1.55%2C2.561-4.34%2C3.534-7.498%2C2.705C288.263%2C245.188%2C292.097%2C243.758%2C293.981%2C244.92z%20M248.437%2C227.56%0A%09%09c12.131-14.045%2C24.535-27.843%2C37.875-40.761c3.271-3.167%2C6.804-6.078%2C10.36-8.927c0.926-0.742%2C2.391-0.812%2C3.608-1.19%0A%09%09c-0.186%2C1.255-0.092%2C2.641-0.604%2C3.744c-2.639%2C5.683-6.643%2C10.459-10.689%2C15.148c-15.378%2C17.818-33%2C33.148-52.203%2C46.7%0A%09%09c-0.138%2C0.097-0.289%2C0.177-0.434%2C0.264c-0.093-0.069-0.186-0.138-0.279-0.207C240.188%2C237.404%2C244.24%2C232.419%2C248.437%2C227.56z%0A%09%09%20M415.185%2C258.07c-0.957%2C0.581-2.187%2C0.79-3.322%2C0.978c-1.224%2C0.203-1.609-0.534-1.193-1.606c0.248-0.64%2C0.62-1.272%2C1.075-1.784%0A%09%09c4.271-4.81%2C9.483-8.261%2C15.534-10.39c2.689-0.946%2C4.195-0.509%2C5.849%2C1.659C427.067%2C250.708%2C421.158%2C254.443%2C415.185%2C258.07z%0A%09%09%20M539.525%2C180.311c-2.66%2C5.675-6.643%2C10.468-10.688%2C15.17c-15.286%2C17.771-32.86%2C33.008-51.928%2C46.571%0A%09%09c-0.265%2C0.189-0.553%2C0.345-0.831%2C0.517c-0.068-0.073-0.137-0.147-0.205-0.22c2.179-2.638%2C4.341-5.289%2C6.538-7.91%0A%09%09c13.891-16.575%2C28.319-32.662%2C43.806-47.769c3.261-3.181%2C6.826-6.063%2C10.389-8.91c0.876-0.7%2C2.294-0.724%2C3.462-1.059%0A%09%09C539.903%2C177.912%2C540.02%2C179.255%2C539.525%2C180.311z%22%2F%3E%0A%09%3Cpath%20stroke%3D%22%23F7F4EE%22%20fill%3D%22%23F7F4EE%22%20stroke-linecap%3D%22round%22%20stroke-linejoin%3D%22round%22%20stroke-miterlimit%3D%2210%22%20d%3D%22M164.891%2C223.747%0A%09%09c4.502-0.235%2C9.013-0.436%2C13.52-0.429c9.663%2C0.016%2C19.326%2C0.179%2C28.989%2C0.23c0.494%2C0.003%2C0.991-0.475%2C1.486-0.73%0A%09%09c-0.488-0.336-0.974-0.96-1.466-0.965c-12.297-0.126-24.594-0.196-36.892-0.247c-1.619-0.007-3.239%2C0.142-5.293%2C0.24%0A%09%09c0.609-0.742%2C0.891-1.11%2C1.198-1.455c8.602-9.669%2C17.216-19.327%2C25.777-29.032c0.422-0.478%2C0.371-1.373%2C0.541-2.074%0A%09%09c-0.635%2C0.225-1.481%2C0.263-1.875%2C0.704c-9.162%2C10.267-18.263%2C20.59-27.43%2C30.854c-0.545%2C0.61-1.526%2C1.095-2.34%2C1.154%0A%09%09c-3.736%2C0.273-7.496%2C0.242-11.227%2C0.56c-10.083%2C0.859-20.158%2C1.823-30.228%2C2.823c-0.523%2C0.052-0.975%2C0.827-1.459%2C1.266%0A%09%09c0.571%2C0.226%2C1.164%2C0.688%2C1.71%2C0.638c2.385-0.22%2C4.749-0.667%2C7.134-0.89c7.515-0.703%2C15.032-1.383%2C22.555-1.988%0A%09%09c3.584-0.288%2C7.184-0.387%2C11.162-0.592c-0.505%2C0.655-0.732%2C0.969-0.978%2C1.266c-3.84%2C4.65-7.731%2C9.259-11.516%2C13.953%0A%09%09c-16.026%2C19.874-31.573%2C40.104-45.334%2C61.644c-0.502%2C0.786-0.996%2C1.594-1.353%2C2.45c-0.14%2C0.335-0.034%2C1%2C0.216%2C1.208%0A%09%09c0.273%2C0.227%2C0.91%2C0.25%2C1.264%2C0.089c0.448-0.204%2C0.891-0.618%2C1.126-1.055c0.718-1.335%2C1.204-2.808%2C2.011-4.081%0A%09%09c16.722-26.362%2C36.167-50.669%2C56.323-74.433C163.034%2C224.24%2C164.07%2C223.79%2C164.891%2C223.747z%22%2F%3E%0A%3C%2Fg%3E%0A%3C%2Fsvg%3E)
%20%20--%3E%0A%3Csvg%20width%3D%22913%22%20height%3D%22292%22%20version%3D%221.1%22%20id%3D%22Layer_1%22%20xmlns%3D%22http%3A%2F%2Fwww.w3.org%2F2000%2Fsvg%22%20xmlns%3Axlink%3D%22http%3A%2F%2Fwww.w3.org%2F1999%2Fxlink%22%20x%3D%220px%22%20y%3D%220px%22%0A%09%20viewBox%3D%2293.51%20166.38%20456.61%20146.15%22%20%20xml%3Aspace%3D%22preserve%22%3E%0A%3Cg%3E%0A%09%3Cpath%20stroke%3D%22%23A9BCD3%22%20fill%3D%22%23A9BCD3%22%20stroke-linecap%3D%22round%22%20stroke-linejoin%3D%22round%22%20stroke-miterlimit%3D%2210%22%20d%3D%22M538.569%2C174.679%0A%09%09c-1.453%2C0.551-2.921%2C1.302-4.098%2C2.3c-4.06%2C3.444-8.158%2C6.87-11.95%2C10.598c-18.233%2C17.929-34.971%2C37.204-51.035%2C57.079%0A%09%09c-0.909%2C1.125-1.924%2C2.245-3.102%2C3.06c-7.23%2C4.999-15.157%2C8.547-23.608%2C10.901c-1.781%2C0.496-3.687%2C0.754-5.534%2C0.748%0A%09%09c-2.912-0.008-4.191-1.702-3.506-4.507c0.341-1.398%2C0.93-2.778%2C1.641-4.033c1.151-2.033%2C2.556-3.923%2C3.731-5.944%0A%09%09c0.537-0.923%2C1.887-1.996%2C0.692-3.017c-0.45-0.384-2.016%2C0.244-2.899%2C0.727c-1.47%2C0.804-2.801%2C1.864-4.253%2C2.859%0A%09%09c-2.031-2.727-4.723-2.911-7.593-1.972c-1.823%2C0.597-3.645%2C1.301-5.323%2C2.221c-3.789%2C2.078-7.429%2C4.429-11.238%2C6.467%0A%09%09c-4.86%2C2.6-9.911%2C4.754-15.492%2C5.291c-2.817%2C0.271-3.375-0.38-2.78-3.172c0.644-3.026%2C1.416-6.035%2C1.871-9.09%0A%09%09c0.381-2.561-0.895-3.716-3.407-3.103c-2.136%2C0.521-4.359%2C1.139-6.22%2C2.253c-6.066%2C3.631-11.983%2C7.512-17.962%2C11.289%0A%09%09c-0.481%2C0.304-1%2C0.547-1.501%2C0.818c-0.088-0.682%2C0.013-1.078%2C0.243-1.374c4.748-6.111%2C9.635-12.098%2C15.671-17.024%0A%09%09c0.544-0.444%2C1.187-0.798%2C1.631-1.323c0.279-0.33%2C0.273-0.901%2C0.396-1.364c-0.519-0.016-1.053-0.111-1.553-0.02%0A%09%09c-0.309%2C0.056-0.591%2C0.367-0.845%2C0.607c-2.768%2C2.606-5.531%2C5.218-8.288%2C7.835c-1.142%2C1.084-2.114%2C2.442-3.43%2C3.229%0A%09%09c-4.109%2C2.458-8.212%2C5.006-12.575%2C6.936c-3.588%2C1.587-7.495%2C2.569-11.351%2C3.395c-3.136%2C0.672-3.755-0.251-3.044-3.467%0A%09%09c0.605-2.737%2C1.254-5.465%2C1.817-8.211c0.579-2.822-0.764-4.208-3.614-3.533c-1.971%2C0.467-4.027%2C1.024-5.739%2C2.052%0A%09%09c-6.061%2C3.639-11.989%2C7.501-17.973%2C11.268c-0.574%2C0.361-1.192%2C0.654-1.79%2C0.978c-0.071-0.699%2C0.046-1.092%2C0.283-1.392%0A%09%09c5.078-6.444%2C10.212-12.834%2C16.774-17.897c0.482-0.372%2C0.611-1.203%2C0.904-1.82c-0.666%2C0.108-1.548-0.02-1.964%2C0.361%0A%09%09c-3.317%2C3.043-6.533%2C6.195-9.807%2C9.286c-1.185%2C1.118-2.338%2C2.316-3.684%2C3.21c-7.828%2C5.202-16.464%2C8.594-25.548%2C10.785%0A%09%09c-2.547%2C0.614-5.327%2C0.614-7.962%2C0.405c-2.538-0.201-3.629-2.047-2.709-4.402c0.728-1.864%2C1.968-3.541%2C3.101-5.22%0A%09%09c0.206-0.306%2C1.024-0.381%2C1.506-0.288c3.123%2C0.604%2C6.049%2C0.397%2C8.647-1.69c1.306-1.049%2C2.131-2.336%2C1.432-3.957%0A%09%09c-0.699-1.62-2.242-1.642-3.775-1.401c-2.846%2C0.448-4.874%2C2.344-7.174%2C3.845c-8.31%2C5.42-17.164%2C9.783-26.663%2C12.709%0A%09%09c-2.204%2C0.679-4.582%2C0.993-6.893%2C1.075c-2.423%2C0.086-3.431-1.241-3.162-3.567c0.079-0.687%2C0.302-1.366%2C0.527-2.025%0A%09%09c0.809-2.375%2C1.795-4.701%2C2.438-7.12c0.797-2.996-0.853-4.569-3.739-3.492c-2.054%2C0.766-4.177%2C1.745-5.819%2C3.153%0A%09%09c-7.018%2C6.014-13.868%2C12.224-20.782%2C18.36c-0.52%2C0.461-1.058%2C0.903-1.588%2C1.354c-0.114-0.103-0.229-0.205-0.343-0.307%0A%09%09c0.336-0.647%2C0.598-1.347%2C1.019-1.934c3.817-5.328%2C7.653-10.642%2C11.515-15.938c0.366-0.502%2C0.908-0.91%2C1.438-1.255%0A%09%09c18.004-11.719%2C34.253-25.54%2C49.035-41.092c6.577-6.92%2C12.982-14.013%2C18.027-22.183c1.037-1.679%2C2.026-3.468%2C2.567-5.341%0A%09%09c0.302-1.047-0.026-2.623-0.68-3.511c-0.827-1.123-2.332-0.852-3.543-0.192c-1.076%2C0.586-2.193%2C1.153-3.133%2C1.923%0A%09%09c-2.851%2C2.337-5.742%2C4.643-8.408%2C7.182c-17.503%2C16.672-33.501%2C34.738-48.767%2C53.442c-4.973%2C6.092-10.053%2C11.842-17.166%2C15.455%0A%09%09c-3.382%2C1.718-6.706%2C3.563-10.156%2C5.13c-1.392%2C0.633-3.04%2C0.792-4.594%2C0.956c-1.449%2C0.152-2.371-0.521-2.183-2.172%0A%09%09c0.119-1.044%2C0.246-2.088%2C0.323-3.135c0.331-4.51-0.973-5.513-5.114-3.526c-3.628%2C1.74-7.065%2C3.877-10.599%2C5.816%0A%09%09c-0.542%2C0.297-1.152%2C0.471-1.73%2C0.703c0.056-0.925%2C0.336-1.49%2C0.668-2.024c1.604-2.585%2C3.283-5.126%2C4.812-7.755%0A%09%09c0.906-1.558%2C1.698-3.207%2C2.33-4.894c0.674-1.797-0.236-3.288-2.139-3.31c-1.521-0.018-3.248%2C0.161-4.534%2C0.879%0A%09%09c-2.95%2C1.648-5.803%2C3.526-8.486%2C5.585c-5.387%2C4.134-10.627%2C8.459-15.949%2C12.679c-0.599%2C0.475-1.331%2C0.782-2.001%2C1.167%0A%09%09c-0.115-0.16-0.229-0.319-0.344-0.479c0.336-0.592%2C0.593-1.25%2C1.02-1.766c3.538-4.278%2C7.105-8.531%2C10.671-12.785%0A%09%09c0.299-0.357%2C0.745-0.614%2C0.97-1.005c0.174-0.301%2C0.279-0.922%2C0.113-1.076c-0.284-0.264-0.827-0.412-1.218-0.348%0A%09%09c-0.348%2C0.057-0.666%2C0.44-0.949%2C0.727c-4.703%2C4.764-9.006%2C9.851-12.485%2C15.594c-0.362%2C0.597-0.798%2C1.219-0.907%2C1.877%0A%09%09c-0.103%2C0.618-0.035%2C1.578%2C0.354%2C1.884c0.46%2C0.362%2C1.46%2C0.44%2C2.021%2C0.187c1.156-0.522%2C2.239-1.266%2C3.242-2.059%0A%09%09c5.33-4.209%2C10.548-8.565%2C15.965-12.657c3.065-2.315%2C6.396-4.292%2C9.704-6.257c0.737-0.438%2C1.883-0.187%2C2.84-0.253%0A%09%09c-0.131%2C0.923-0.063%2C1.938-0.435%2C2.75c-0.776%2C1.695-1.734%2C3.315-2.709%2C4.91c-1.464%2C2.395-3.037%2C4.724-4.496%2C7.122%0A%09%09c-0.447%2C0.735-0.806%2C1.579-0.972%2C2.419c-0.292%2C1.482%2C0.464%2C2.193%2C1.88%2C1.668c1.462-0.543%2C2.844-1.333%2C4.207-2.109%0A%09%09c3.2-1.821%2C6.34-3.748%2C9.566-5.521c0.838-0.461%2C1.9-0.513%2C2.99-0.786c-0.175%2C2.374-0.435%2C4.348-0.436%2C6.322%0A%09%09c-0.001%2C2.282%2C1.081%2C3.517%2C3.342%2C3.343c2.464-0.189%2C5.086-0.498%2C7.286-1.516c4.652-2.153%2C9.075-4.801%2C13.704-7.307%0A%09%09c-0.308%2C0.439-0.612%2C0.852-0.894%2C1.279c-2.865%2C4.342-5.755%2C8.668-8.564%2C13.046c-0.589%2C0.918-1.002%2C2-1.254%2C3.064%0A%09%09c-0.137%2C0.579%2C0.037%2C1.571%2C0.434%2C1.84c0.385%2C0.261%2C1.323-0.014%2C1.859-0.326c0.691-0.402%2C1.231-1.068%2C1.822-1.634%0A%09%09c5.245-5.021%2C10.361-10.185%2C15.776-15.015c3.257-2.905%2C6.928-5.361%2C10.526-7.857c0.843-0.585%2C2.14-0.517%2C3.228-0.75%0A%09%09c-0.154%2C1.061-0.184%2C2.159-0.486%2C3.176c-0.764%2C2.568-1.884%2C5.051-2.428%2C7.658c-0.659%2C3.164%2C1.057%2C5.349%2C4.276%2C5.502%0A%09%09c2.186%2C0.104%2C4.463-0.104%2C6.588-0.624c7.614-1.864%2C14.511-5.491%2C21.409-9.084c0.53-0.276%2C1.074-0.524%2C1.841-0.897%0A%09%09c-0.421%2C0.94-0.733%2C1.565-0.985%2C2.212c-1.629%2C4.197%2C0.212%2C7.45%2C4.698%2C7.952c2.007%2C0.225%2C4.119%2C0.21%2C6.099-0.156%0A%09%09c8.113-1.497%2C15.707-4.489%2C22.95-8.406c0.467-0.253%2C0.949-0.48%2C1.73-0.874c-1.614%2C2.355-3.084%2C4.331-4.339%2C6.435%0A%09%09c-0.363%2C0.609-0.107%2C1.586-0.135%2C2.394c0.801-0.096%2C1.748%2C0.049%2C2.374-0.333c1.793-1.096%2C3.413-2.471%2C5.177-3.619%0A%09%09c5.831-3.793%2C11.647-7.614%2C17.58-11.242c1.543-0.943%2C3.47-1.299%2C5.26-1.782c1.016-0.274%2C1.576%2C0.248%2C1.331%2C1.375%0A%09%09c-0.099%2C0.457-0.191%2C0.915-0.297%2C1.37c-0.618%2C2.675-1.279%2C5.341-1.85%2C8.026c-0.665%2C3.13%2C0.652%2C4.737%2C3.867%2C4.676%0A%09%09c1.278-0.024%2C2.571-0.204%2C3.822-0.477c5.826-1.272%2C11.139-3.84%2C16.375-6.589c0.426-0.224%2C0.874-0.408%2C1.691-0.786%0A%09%09c-1.58%2C2.247-2.922%2C4.091-4.19%2C5.984c-0.695%2C1.037-1.855%2C2.301-0.591%2C3.404c1.182%2C1.031%2C2.213-0.347%2C3.196-0.998%0A%09%09c6.874-4.554%2C13.698-9.185%2C20.648-13.618c1.731-1.104%2C3.819-1.755%2C5.829-2.283c1.842-0.483%2C2.227%2C0.076%2C1.807%2C1.916%0A%09%09c-0.688%2C3.019-1.412%2C6.03-2.049%2C9.06c-0.585%2C2.783%2C0.608%2C4.279%2C3.442%2C4.395c0.697%2C0.029%2C1.441%2C0.059%2C2.093-0.141%0A%09%09c4.173-1.279%2C8.328-2.619%2C12.485-3.95c0.551-0.176%2C1.082-0.414%2C1.898-0.729c-0.403%2C0.736-0.647%2C1.133-0.844%2C1.551%0A%09%09c-0.621%2C1.315-1.206%2C2.914-0.026%2C3.912c0.861%2C0.729%2C2.519%2C1.06%2C3.649%2C0.805c1.954-0.441%2C3.935-1.224%2C5.622-2.305%0A%09%09c5.614-3.595%2C11.102-7.386%2C16.638-11.103c0.92-0.618%2C1.839-1.237%2C2.758-1.856c-0.788%2C1.986-1.969%2C3.628-2.665%2C5.455%0A%09%09c-0.712%2C1.869-1.187%2C3.902-1.331%2C5.894c-0.157%2C2.185%2C1.313%2C3.811%2C3.455%2C4.218c1.19%2C0.226%2C2.454%2C0.309%2C3.657%2C0.186%0A%09%09c5.068-0.521%2C9.73-2.451%2C14.331-4.466c3.507-1.536%2C6.898-3.334%2C10.614-5.149c-0.422%2C0.635-0.691%2C1.044-0.966%2C1.45%0A%09%09c-2.591%2C3.826-5.249%2C7.61-7.741%2C11.5c-0.934%2C1.458-1.572%2C3.131-2.151%2C4.775c-0.181%2C0.512%2C0.097%2C1.438%2C0.501%2C1.815%0A%09%09c0.263%2C0.245%2C1.208-0.024%2C1.71-0.307c0.647-0.365%2C1.182-0.949%2C1.721-1.483c1.956-1.936%2C3.805-3.99%2C5.854-5.819%0A%09%09c5.893-5.258%2C11.816-10.485%2C17.842-15.588c1.345-1.139%2C3.12-1.818%2C4.775-2.525c1.104-0.472%2C1.76%2C0.084%2C1.374%2C1.309%0A%09%09c-0.525%2C1.669-1.269%2C3.273-1.732%2C4.957c-0.551%2C2.005-1.184%2C4.054-1.268%2C6.104c-0.097%2C2.368%2C1.38%2C3.81%2C3.778%2C4.016%0A%09%09c1.73%2C0.149%2C3.555%2C0.204%2C5.229-0.176c10.868-2.464%2C20.485-7.78%2C29.928-13.445c0.375-0.225%2C0.471-0.915%2C0.698-1.388%0A%09%09c-0.572-0.065-1.154-0.224-1.712-0.163c-0.368%2C0.04-0.7%2C0.398-1.049%2C0.614c-7.434%2C4.6-15.223%2C8.484-23.555%2C11.154%0A%09%09c-2.641%2C0.846-5.451%2C1.368-8.217%2C1.563c-2.748%2C0.194-3.899-1.561-3.252-4.255c0.122-0.508%2C0.346-0.992%2C0.52-1.488%0A%09%09c0.794-2.258%2C1.755-4.476%2C2.305-6.792c0.25-1.049%2C0.051-2.653-0.622-3.337c-0.584-0.593-2.268-0.608-3.214-0.236%0A%09%09c-1.991%2C0.782-4.068%2C1.692-5.666%2C3.065c-7.01%2C6.024-13.861%2C12.233-20.772%2C18.371c-0.524%2C0.465-1.067%2C0.909-1.601%2C1.363%0A%09%09c-0.116-0.1-0.233-0.199-0.349-0.299c0.335-0.645%2C0.598-1.341%2C1.016-1.927c3.706-5.192%2C7.426-10.373%2C11.181-15.53%0A%09%09c0.471-0.647%2C1.1-1.235%2C1.771-1.674c20.852-13.66%2C39.424-29.938%2C55.89-48.634c4.727-5.366%2C9.27-10.882%2C12.66-17.223%0A%09%09c0.669-1.252%2C1.139-2.717%2C1.271-4.125C542.312%2C175.139%2C540.628%2C173.898%2C538.569%2C174.679z%20M293.981%2C244.92%0A%09%09c-1.55%2C2.561-4.34%2C3.534-7.498%2C2.705C288.263%2C245.188%2C292.097%2C243.758%2C293.981%2C244.92z%20M248.437%2C227.56%0A%09%09c12.131-14.045%2C24.535-27.843%2C37.875-40.761c3.271-3.167%2C6.804-6.078%2C10.36-8.927c0.926-0.742%2C2.391-0.812%2C3.608-1.19%0A%09%09c-0.186%2C1.255-0.092%2C2.641-0.604%2C3.744c-2.639%2C5.683-6.643%2C10.459-10.689%2C15.148c-15.378%2C17.818-33%2C33.148-52.203%2C46.7%0A%09%09c-0.138%2C0.097-0.289%2C0.177-0.434%2C0.264c-0.093-0.069-0.186-0.138-0.279-0.207C240.188%2C237.404%2C244.24%2C232.419%2C248.437%2C227.56z%0A%09%09%20M415.185%2C258.07c-0.957%2C0.581-2.187%2C0.79-3.322%2C0.978c-1.224%2C0.203-1.609-0.534-1.193-1.606c0.248-0.64%2C0.62-1.272%2C1.075-1.784%0A%09%09c4.271-4.81%2C9.483-8.261%2C15.534-10.39c2.689-0.946%2C4.195-0.509%2C5.849%2C1.659C427.067%2C250.708%2C421.158%2C254.443%2C415.185%2C258.07z%0A%09%09%20M539.525%2C180.311c-2.66%2C5.675-6.643%2C10.468-10.688%2C15.17c-15.286%2C17.771-32.86%2C33.008-51.928%2C46.571%0A%09%09c-0.265%2C0.189-0.553%2C0.345-0.831%2C0.517c-0.068-0.073-0.137-0.147-0.205-0.22c2.179-2.638%2C4.341-5.289%2C6.538-7.91%0A%09%09c13.891-16.575%2C28.319-32.662%2C43.806-47.769c3.261-3.181%2C6.826-6.063%2C10.389-8.91c0.876-0.7%2C2.294-0.724%2C3.462-1.059%0A%09%09C539.903%2C177.912%2C540.02%2C179.255%2C539.525%2C180.311z%22%2F%3E%0A%09%3Cpath%20stroke%3D%22%23A9BCD3%22%20fill%3D%22%23A9BCD3%22%20stroke-linecap%3D%22round%22%20stroke-linejoin%3D%22round%22%20stroke-miterlimit%3D%2210%22%20d%3D%22M164.891%2C223.747%0A%09%09c4.502-0.235%2C9.013-0.436%2C13.52-0.429c9.663%2C0.016%2C19.326%2C0.179%2C28.989%2C0.23c0.494%2C0.003%2C0.991-0.475%2C1.486-0.73%0A%09%09c-0.488-0.336-0.974-0.96-1.466-0.965c-12.297-0.126-24.594-0.196-36.892-0.247c-1.619-0.007-3.239%2C0.142-5.293%2C0.24%0A%09%09c0.609-0.742%2C0.891-1.11%2C1.198-1.455c8.602-9.669%2C17.216-19.327%2C25.777-29.032c0.422-0.478%2C0.371-1.373%2C0.541-2.074%0A%09%09c-0.635%2C0.225-1.481%2C0.263-1.875%2C0.704c-9.162%2C10.267-18.263%2C20.59-27.43%2C30.854c-0.545%2C0.61-1.526%2C1.095-2.34%2C1.154%0A%09%09c-3.736%2C0.273-7.496%2C0.242-11.227%2C0.56c-10.083%2C0.859-20.158%2C1.823-30.228%2C2.823c-0.523%2C0.052-0.975%2C0.827-1.459%2C1.266%0A%09%09c0.571%2C0.226%2C1.164%2C0.688%2C1.71%2C0.638c2.385-0.22%2C4.749-0.667%2C7.134-0.89c7.515-0.703%2C15.032-1.383%2C22.555-1.988%0A%09%09c3.584-0.288%2C7.184-0.387%2C11.162-0.592c-0.505%2C0.655-0.732%2C0.969-0.978%2C1.266c-3.84%2C4.65-7.731%2C9.259-11.516%2C13.953%0A%09%09c-16.026%2C19.874-31.573%2C40.104-45.334%2C61.644c-0.502%2C0.786-0.996%2C1.594-1.353%2C2.45c-0.14%2C0.335-0.034%2C1%2C0.216%2C1.208%0A%09%09c0.273%2C0.227%2C0.91%2C0.25%2C1.264%2C0.089c0.448-0.204%2C0.891-0.618%2C1.126-1.055c0.718-1.335%2C1.204-2.808%2C2.011-4.081%0A%09%09c16.722-26.362%2C36.167-50.669%2C56.323-74.433C163.034%2C224.24%2C164.07%2C223.79%2C164.891%2C223.747z%22%2F%3E%0A%3C%2Fg%3E%0A%3C%2Fsvg%3E)
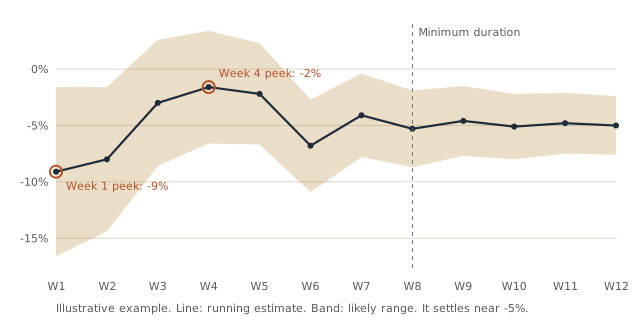
Week one of a geo test. Someone checks the dashboard: the test region is already down 9%. The campaign clearly works. Can we call it?
Week four: down 2%. Week eight: down 5%, where it settles. If you'd called it at week one, you'd have overstated the effect almost twofold. If you'd called it at week four, you might have cut a campaign that works.
Why early results swing
Early in a test there's very little data. A few unusual weeks (a local event, a delivery hiccup, the weather) move the estimate a lot. As weeks accumulate, those bumps average out and the estimate settles.
The range around the estimate tells the same story: very wide at first, narrowing as the test runs.
A test that's checked every week until it looks good will always look good eventually. That's the problem.
Why peeking makes it worse
Looking isn't the problem. Acting on what you see is. If you check every week and stop as soon as the result looks good, you'll stop at a lucky high point far more often than chance suggests. A test that's checked every week until it looks good will always look good eventually.
The same happens in reverse: stop when it looks bad and you'll kill campaigns that work.
How to protect the decision
- Agree the minimum duration before launch, from the power analysis, and write it down.
- Monitor the test's health, not its result. Is spend delivering as planned? Is the data arriving? Has anything contaminated the comparison regions? Those are the things to watch weekly.
- Lock the readout. Some teams literally hide the result until the minimum duration has passed. It feels strict; it saves bad decisions.
- Read out once, at the agreed end, using the analysis you agreed before launch.
What if something goes wrong mid-test?
Stopping early for a real problem (spend leaking into the test region, a major outage) is fine. Stop, record why, and treat the test as incomplete rather than reading a result from it.
The discipline is the point
The value of a test comes from deciding the rules before you see the data. Peeking quietly removes that, and turns a careful experiment back into an opinion with a chart attached.